I’ve tried making automated article writing workflows at least a dozen times in the last three years. Every time, I hit a quality issue that didn’t make me feel comfortable using it. I’ve tested plenty of other ones too, and wasn’t satisfied with them either. I now have one I like that I developed for a passion project of mine, and I’ve adapted it to work for another site too.
My passion project is a college football site. Every week, it has AI write an article for all 138 top-division (FBS) teams. Each one is researched, written, fact-checked and edited, all autonomously, and it just runs on a trigger. It was quite a bit of work to get it to where I wasn’t involved, and getting the articles to sound good took a lot of iteration. It took a lot of subjective involvement and caring about quality and evaluation to get there. These are the lessons from that work.
The biggest thing I learned is that to get AI writing you can publish without a person editing it, you split the job into narrow roles and let code, not another AI, do every check that has to be exact.
Transcript
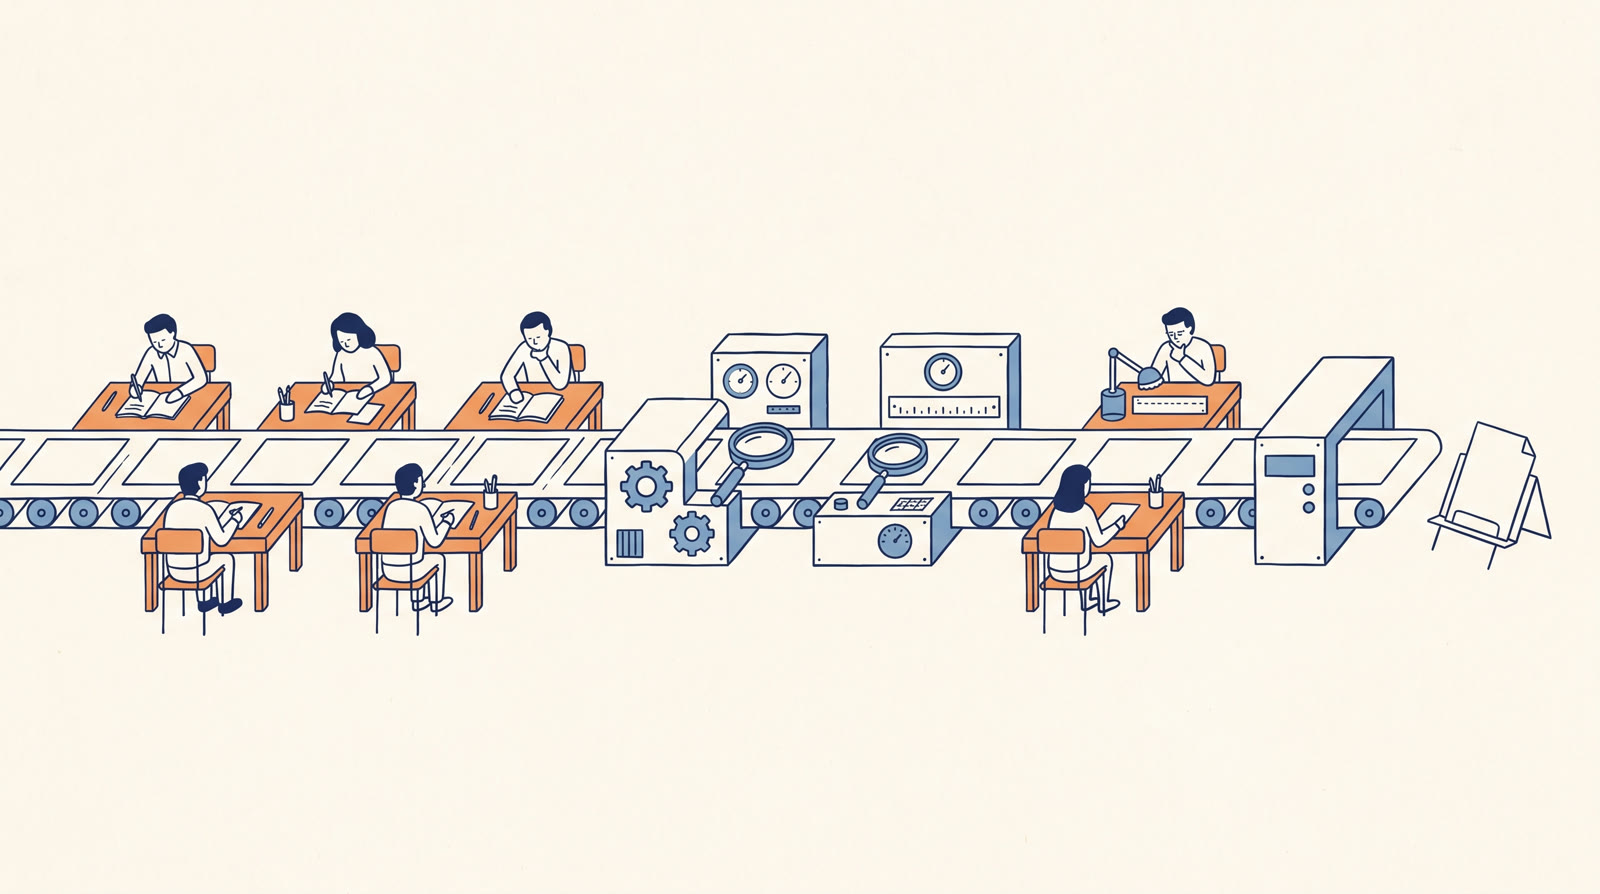
Let's say you ask your AI to write an article. If it writes from memory, it will get some things wrong. Here's how a college football site that covers every top-division team gets from research to a published article, one step at a time. The orange steps are AI. The blue steps are code, plain written-out instructions that give the same answer every time. First, AI researches the team: the head coach, the coordinators, departing seniors, recruits, injuries, and the last few seasons. Every fact gets a source. Then a planner, also AI, looks at 24 of the 138 teams at a time and gives each one a different lead story, so the articles don't all start the same way. Next, another AI step picks just the research that fits this team's story, so the writer isn't buried in facts. The writer drafts the article, and logs every fact it uses, along with its source. The writer kept that log itself, so code checks that every logged sentence is really in the article, character by character. Then an AI checks each fact against passages from its source, because the writer still gets facts wrong. Here, one sentence fails. When a fact fails, the article fixes itself. An AI proposes an edit. Code applies it if it passes code's rules, and cuts the sentence if it doesn't. Then the draft gets checked again. Here, 16 times became 14. Then an AI editor polishes it, but it isn't allowed to rewrite the story or change what the planner intended. Code also searches for known habits that give AI writing away, like em dashes. It sends back only that one line, because an AI fixing the whole article can slip one back in. When the whole batch is done, a last check looks for phrases repeated across articles, like "ready to kick off the 2026 season", so they don't read like a formula. Then it goes live. Since its third week, every article has been released by the pipeline itself, with nobody reading it first. Giving each step one narrow job, and letting code handle every check that has to be exact, is what lets this site write and check an article for all 138 teams every week, with nobody editing them.
How close it is to running on its own
It didn’t start out hands-off. In week 1, 120 of the 138 articles went live after I reviewed and approved them. Since week 3, every article that went live was released by the pipeline itself, with nobody reading it first. Weeks 5 and 6 still needed hand-written recovery scripts to get the runs finished.
In week 7, I think the only thing that kept it from being fully automatic was that the trigger didn’t work. Otherwise it went smoothly, with relatively few issues. It took the least time and the fewest tokens, because it wasn’t redoing steps that didn’t need to be redone. By 6:20 PM Sunday, 137 of the 138 were live. (Well, technically I hit a usage limit and the Georgia Tech article didn’t make it into that run, but I’m calling it a victory anyway.) The release ran 9.4 hours, against 24.9 in week 5 and 21.3 in week 6, and the model calls reported about $4.57 per published article at API prices, failed attempts included.
This works because the articles are objective
My co-founder, Jason Glaspey, pointed out one of the big reasons I can stay out of it. “These articles are objective articles. And not subjective articles,” he said. They’re “an assemblage of fact.” If we were releasing opinion, “we would be involved because we would want to make sure that the subjectiveness matched ours.”
Don’t ask a chat window to write from memory
A bad idea would be to go to AI and say, “Hey, write me an article about Boston College.” Then it does whatever it interprets your vague request to be.
Think about asking a human to do the task. If you say, “I want you to write me an article, but only from your memory,” you’re gonna get some things wrong. So how does a human deal with it? They look up the information. You need a research step, and then you need to fact-check it, just like they do in reputable publications. Reputable being a keyword.
So this doesn’t work like a chat with ChatGPT. It runs as code, as a series of steps, and the first step is research.
Give the writer only what the story needs
Because it’s college football, there’s a pretty limited set of things to research. Is the head coach the same? Is the offensive coordinator the same? The defensive coordinator? What seniors have departed? What’s the incoming recruiting class like? Any known injuries? How did they do last season, and what’s the trend been over the last three years? That makes the research dossier, and everything in it is cited.
Then a slate planner takes 24 teams at a time and figures out who’s the most deserving of different storylines, so the articles aren’t all starting the same way or overusing the same storylines. It kind of plans like, oh, your head coaching change is more important, so I’m going to make that the lead for you.
Then another AI step grabs the slate plan for each team and selects from the dossier just the research that goes with the planned story, so it doesn’t overwhelm the writer.
Let code do the checks that have to be exact
Every time the writer uses a fact from the dossier, it records it in a JSON file, a simple log. Here’s the snippet. Here’s the source.
The first check is whether the sentence the writer registered actually appears in the article. It checks byte for byte, not word for word. And because it checks using deterministic code, plain code that gives the same answer every time, instead of the AI model, it’s infallible. If you give it to a probabilistic model, it’ll sometimes be like, oh, yeah, that’s the sentence, even though the two were off by a couple of words.
Transcript
Let's say you, or your AI, did some research. Then you used that research in a prompt to write something, like a blog post. Now suppose you want to fact-check it. First, you need to know which sentence used which fact. So as your AI writes, have it log each fact it uses, and the exact sentence it went into. But your AI wrote that log too. So before you trust it, check that each logged sentence actually appears in the article. A common way is to just ask your AI: is this sentence really in the article? But here's the problem. LLMs are probabilistic, so sometimes it justifies an error, kinda like humans do. You wouldn't check the same sentence over and over. But you will check a lot of facts over time, and some of those answers will be wrong. When it comes to fact-checking, getting the answer wrong some of the time isn't acceptable. So this is where the byte-for-byte technique can help. Every character is stored as a number, called a byte. For example, t is stored as 116, and a is stored as 97. Code compares those numbers, one by one. Same input, same answer, every time. The byte-for-byte method is a great way to make sure your fact logs match your writing. It gets the answer right every time, runs blazing fast, and doesn't cost any more tokens.
Don’t trust a model that says it “checked”
The second check is whether the fact is used correctly, and for that another AI comes in and looks at it. Just because you have a source, just because you link to it, did you actually use it in the way the source says? Stanford researchers found that gap in commercially available legal research tools they tested in 2024. They count a claim that is “cited but misinterpret[s] the source” as a hallucination, and even with citations, those tools hallucinated “between 17% and 33% of the time.”
I’ve seen this kind of check miss. The first version of it had a model with web access read the sources itself, and it vouched for URLs it never opened, with 8 web actions for 14 facts citing more than 20 URLs. The old web tool also couldn’t read large school athletics pages or PDFs that a plain request returns in full. Now code fetches each cited page and hands the model only the passages that bear on each claim. That fixes it because fetching a page is an exact job, so code does it, and the model has no tools of its own, so it can’t say it opened something it didn’t. The video below walks through how that works. With the new check in place, articles that had been passing the old one turned out to have “coach characterizations and quotes that appear in no cited source.” On a replay of six articles against the old checker, every one of the 59 cited pages got read, with 78% fewer input tokens per article.
Transcript
Let's say your AI wrote an article, and it linked a source for every fact. Now you want to know if each fact really matches what its source says. A common way is to give your AI a web tool, so it can open pages on its own, and ask it to check. It comes back and says it checked every source. But you only have its word for that. You can't see which pages it actually read. Here's a real example, from a site that writes about college football. The AI used its web tool only 8 times, for 14 facts that cited more than 20 pages. And it vouched for pages it never opened. Its web tool also couldn't read some kinds of pages, like big school athletics pages, or PDFs. So here's a more reliable way. Before any checking starts, code downloads every cited page, the same plain way a browser asks for one, and saves the text. A plain download returns the whole page, so even the athletics pages and PDFs come through. Then, for each fact, code pulls out just the passages that talk about it. On a long page, it finds the lines with the fact's names and numbers, and keeps a line on each side for context. It hands the AI the fact and those passages together. The AI gets no web tool at all. It only reads what it's handed, so it can't say it opened something it didn't. Then it says whether those passages support the fact. When checks ran this way, articles that had passed the old check turned out to have quotes and coach descriptions that appear in no cited source. Having code fetch the pages means every source really gets read, and it costs less too. When six articles were checked both ways, the new way read all 59 cited pages, and used 78% fewer input tokens per article, the units AI use is billed by.
In week 7, 136 of the 137 published articles had at least one fact flagged on the first check, and about a third of all checked facts were flagged. When a fact fails, it heals itself. It doesn’t just reject it. It goes and tweaks it. A model with no tools proposes edits that either correct or remove the passage. Code applies each edit that passes its guards and cuts the sentence behind any edit that doesn’t. Then the draft is checked again, any sentence still wrong gets cut, and the article only moves on when it passes. As a comment in the code puts it, “Deleting text cannot add an unsupported claim.” In week 7, one article said a player “ran 16 times for 114 yards.” The check flagged it, the repair changed it to 14, and the published article says “ran 14 times for 114 yards.” Repairs cut 73 sentences across 51 of the 137 week 7 articles.
Keep the editor from writing
Once the fact check is done, it gets handed to an editor. The editor does a light touch that doesn’t ruin the voice of the writer. It corrects AI slop and does the editing that’s gonna make the article better. It’s basically told it’s not there to rewrite the story or to take away the teeth and smooth out the edges. Don’t try to rewrite things just because you think you’re trying to smooth an edge. Definitely don’t do that because that ruins the writing. You’re not the writer. It’s not allowed to change what the slate planner intended for the article. It looks for stuff like a real editor would, instead of stealing the role of the writer.
Send only the broken line back
There are things AI, because of its weights and balances, just can’t help itself on. The em dash. The setup colon, as in “The real question for this season is: blah, blah, blah.” That’s just an em dash in disguise.
If you give it the whole article and tell it to remove those, it may actually reintroduce one. In November 2025, Sam Altman posted, “If you tell ChatGPT not to use em-dashes in your custom instructions, it finally does what it’s supposed to do!” TechCrunch noted that the change “won’t necessarily eliminate the em dash from its output by default.”
So I programmatically find those, and then I feed just that part back to fix.
In week 5, 300 of the writer’s 308 drafts had an em or en dash in them. After the writer moved to Opus 5.5 for week 7, 1 of 233 did. The setup colon didn’t disappear either. Week 7 still needed 375 colon fixes across 131 of its 137 articles.
When it’s done with the batch, another check comes along and looks for sameness across the articles, like a whole bunch of times, “ready to kick off the 2026 season.” Otherwise, if you read multiple articles, you’re just like, this is a formula.
Now I’m actually starting to be able to spend time on making the site cool again, and not just trying to put all of my tokens and focus into getting the articles done. I do still spot check the content and I read my team’s article every week. I’m pretty impressed with the output and definitely have times when I read a line of copy and think “Damn, that’s a good line!”. I’m excited to push on style more as I apply this process to other projects too.